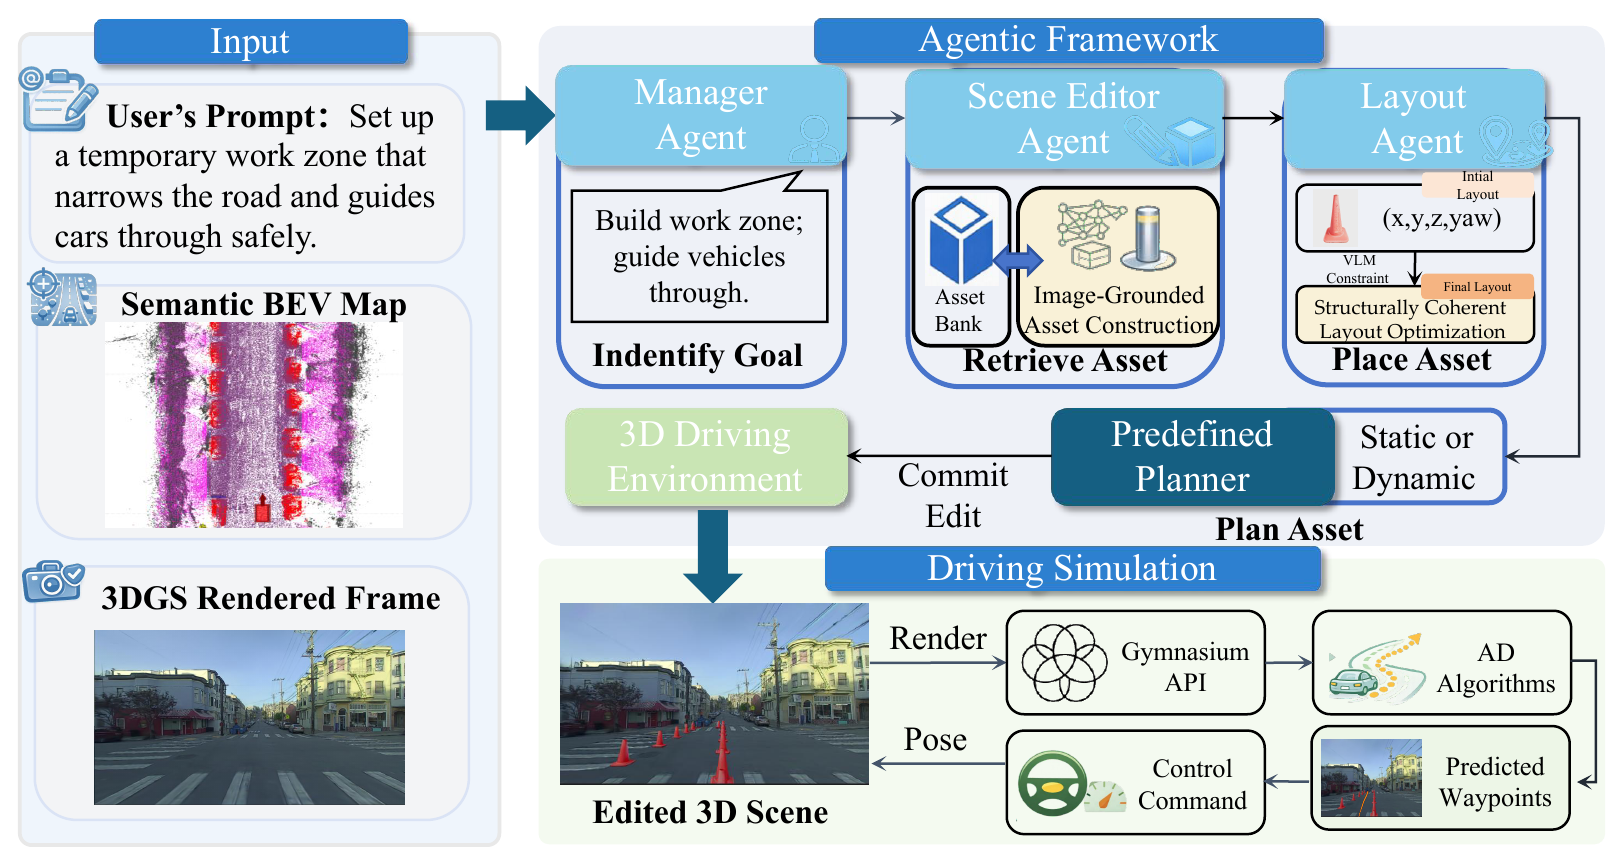
Agentic scene construction framework.
LATTE uses a Manager Agent, Scene Editor Agent, and Layout Agent to translate language requests into executable 3D scene edit programs, then commits the edited scene to a closed-loop simulation environment.
ACM MM 2026
Constructing explicit 3D driving scenarios from open-world language requests, with asset grounding, layout optimization, and closed-loop autonomous-driving evaluation.
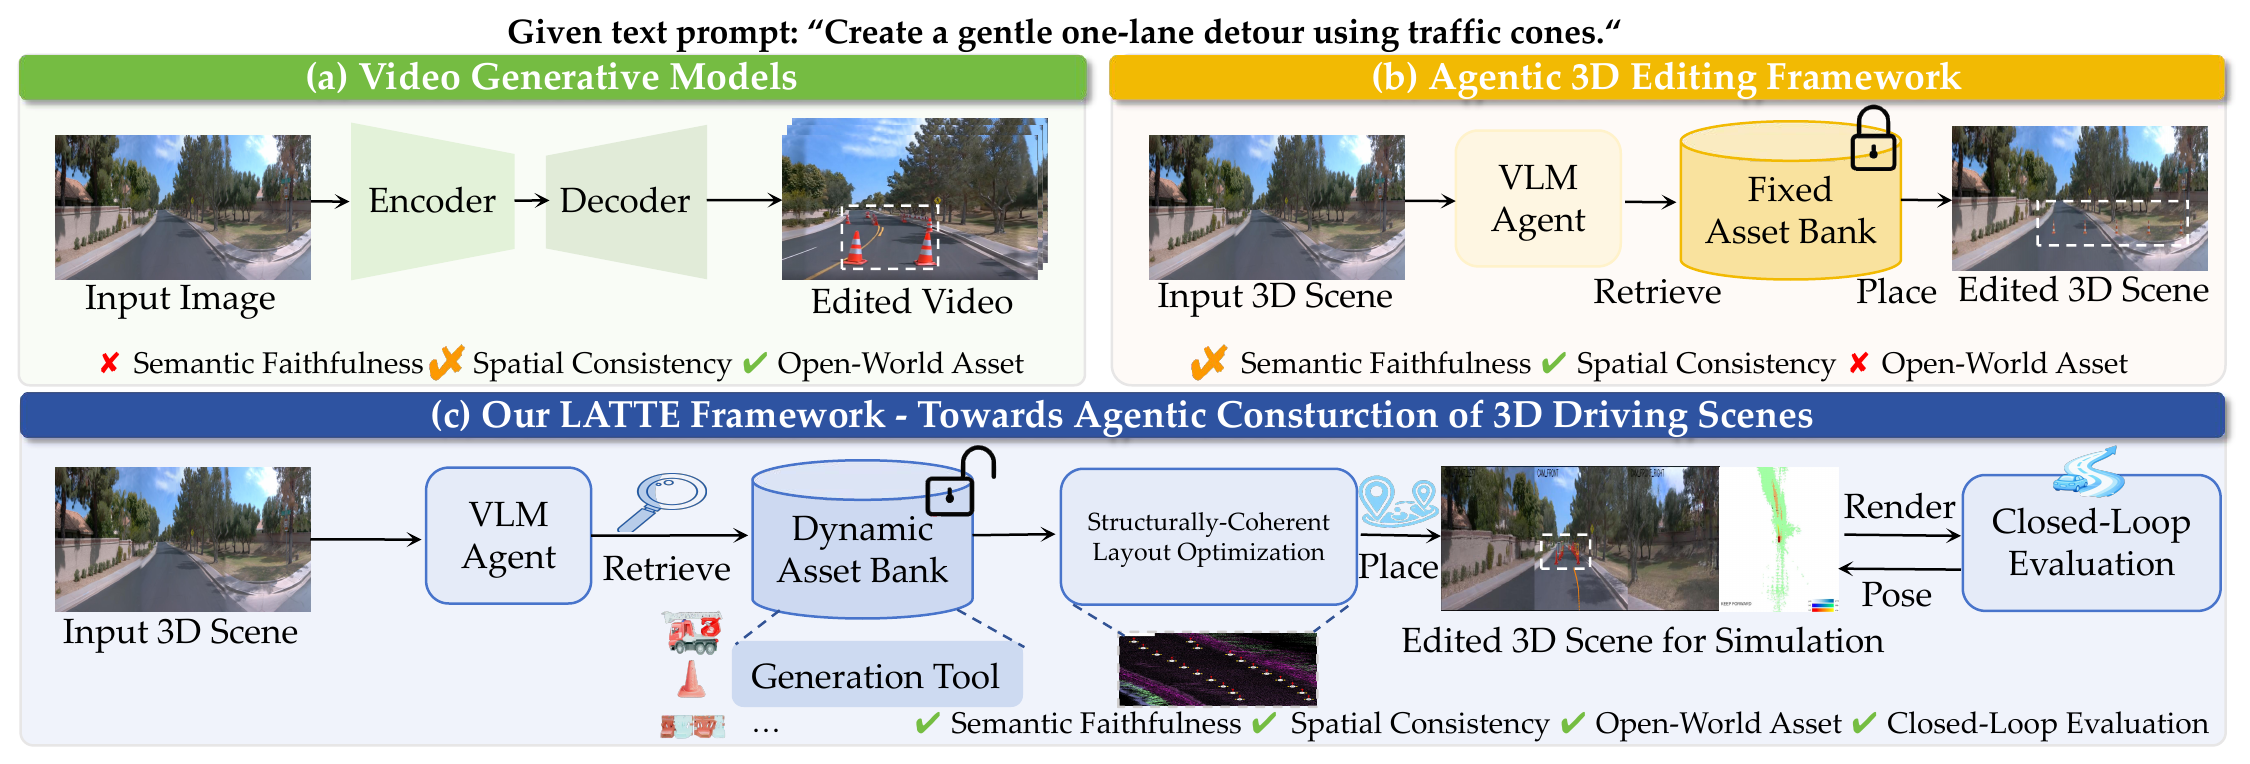
Closed-loop simulation is central to autonomous driving safety evaluation, yet turning natural-language requests into valid 3D test scenarios remains difficult. LATTE decomposes this problem into two coupled stages: Image-Grounded Asset Construction (IGAC), which acquires insertion-ready 3D assets for missing objects from visual evidence, and Structurally Coherent Layout Optimization (SCLO), which turns language-guided placements into simulation-suitable layouts under physical and semantic constraints. The resulting edits are written back to a real-scene-reconstructed simulator and evaluated through closed-loop AD rollouts. Experiments show that LATTE supports open-world asset insertion, produces more coherent scene layouts, and creates behaviorally effective test cases that measurably alter downstream AD performance.
A compact view of the language-agentic construction pipeline.
LATTE uses a Manager Agent, Scene Editor Agent, and Layout Agent to translate language requests into executable 3D scene edit programs, then commits the edited scene to a closed-loop simulation environment.
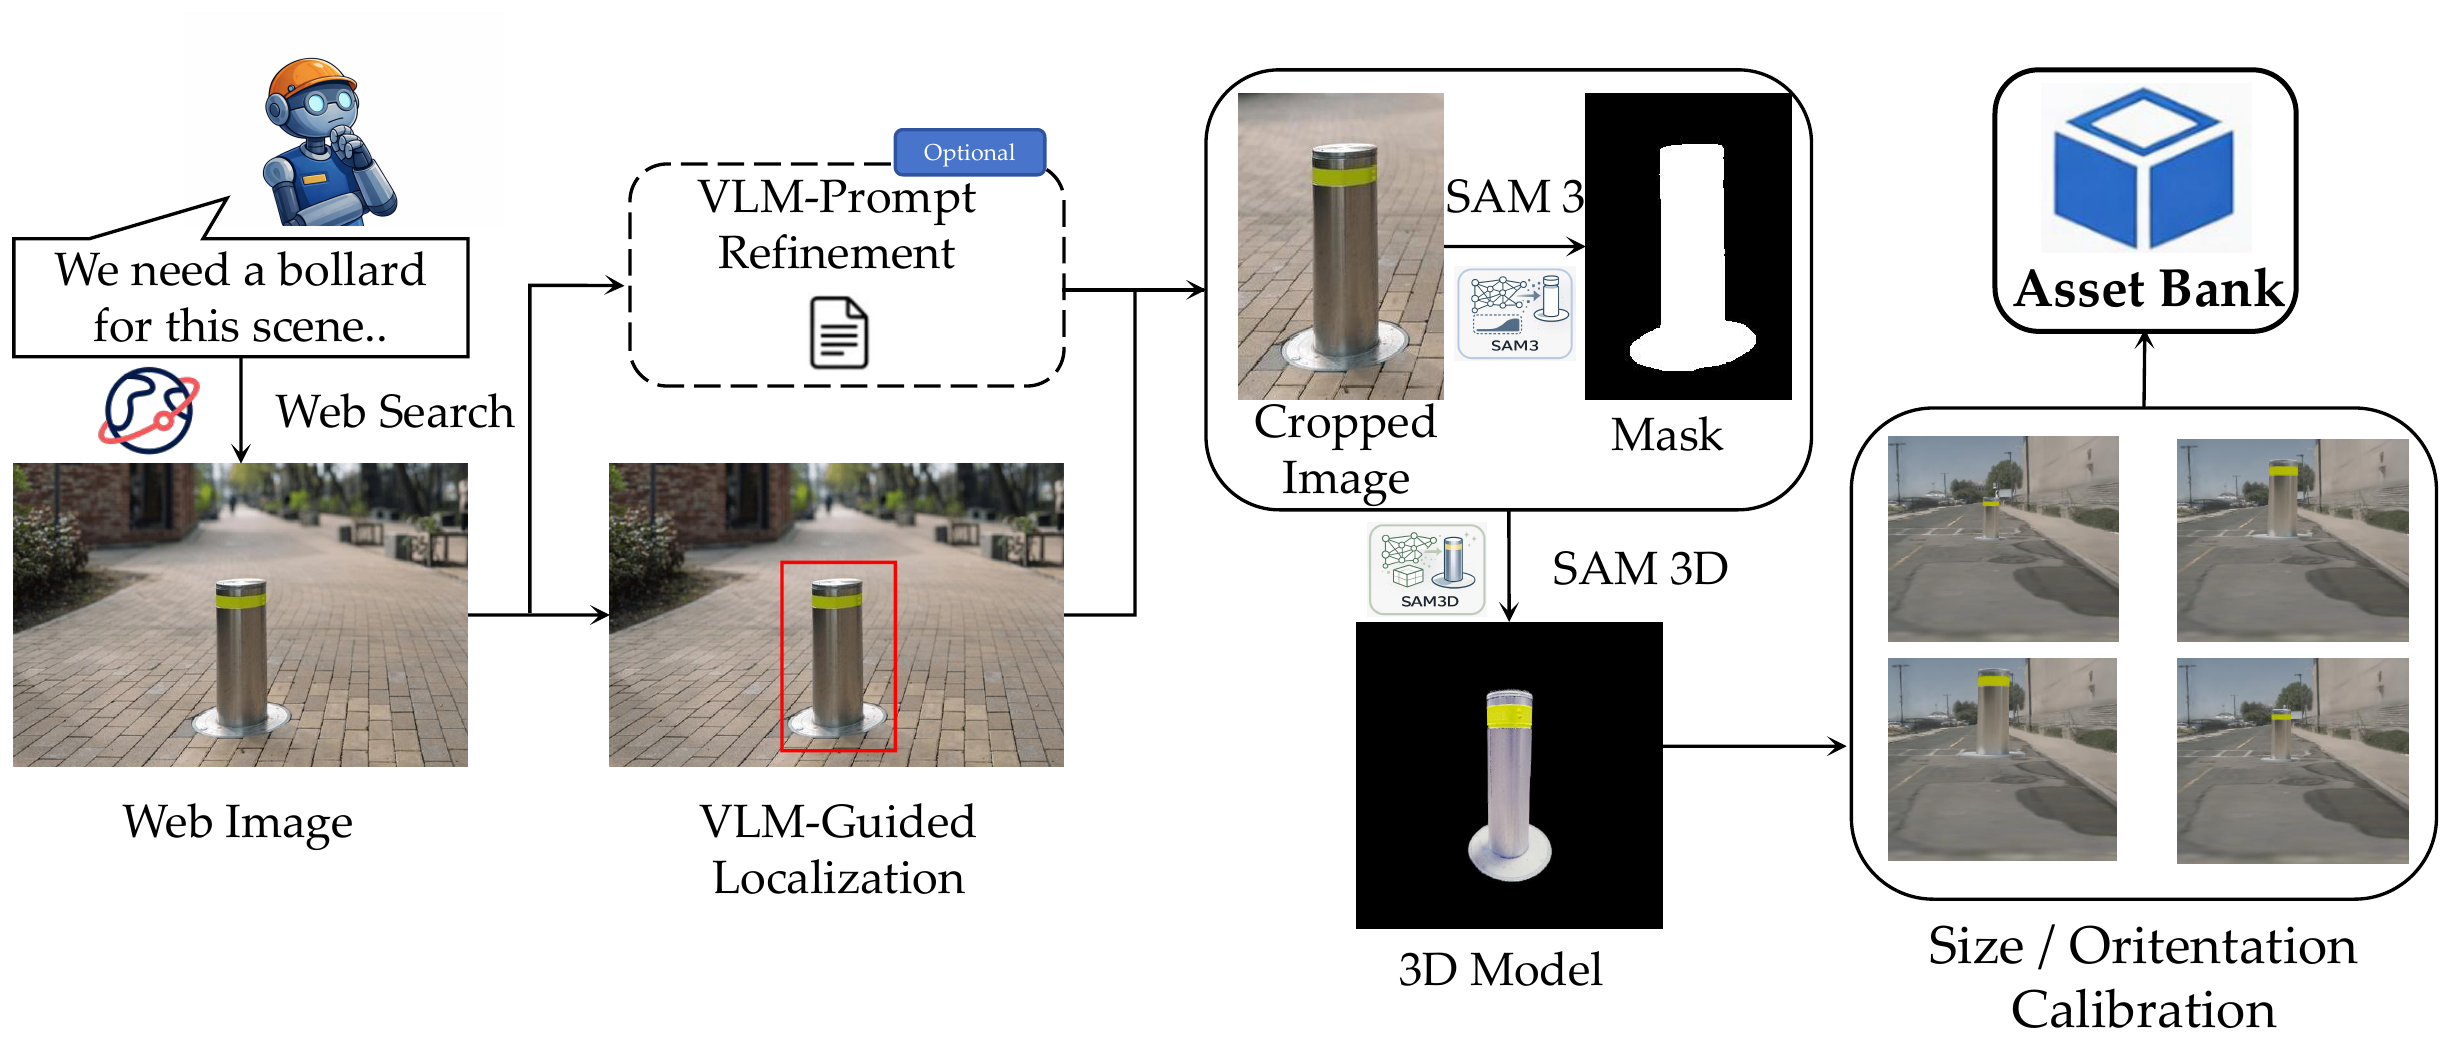
Given an open-world object request, the module grounds the target with web visual evidence and converts it into a simulator-ready 3D asset for downstream scene editing.
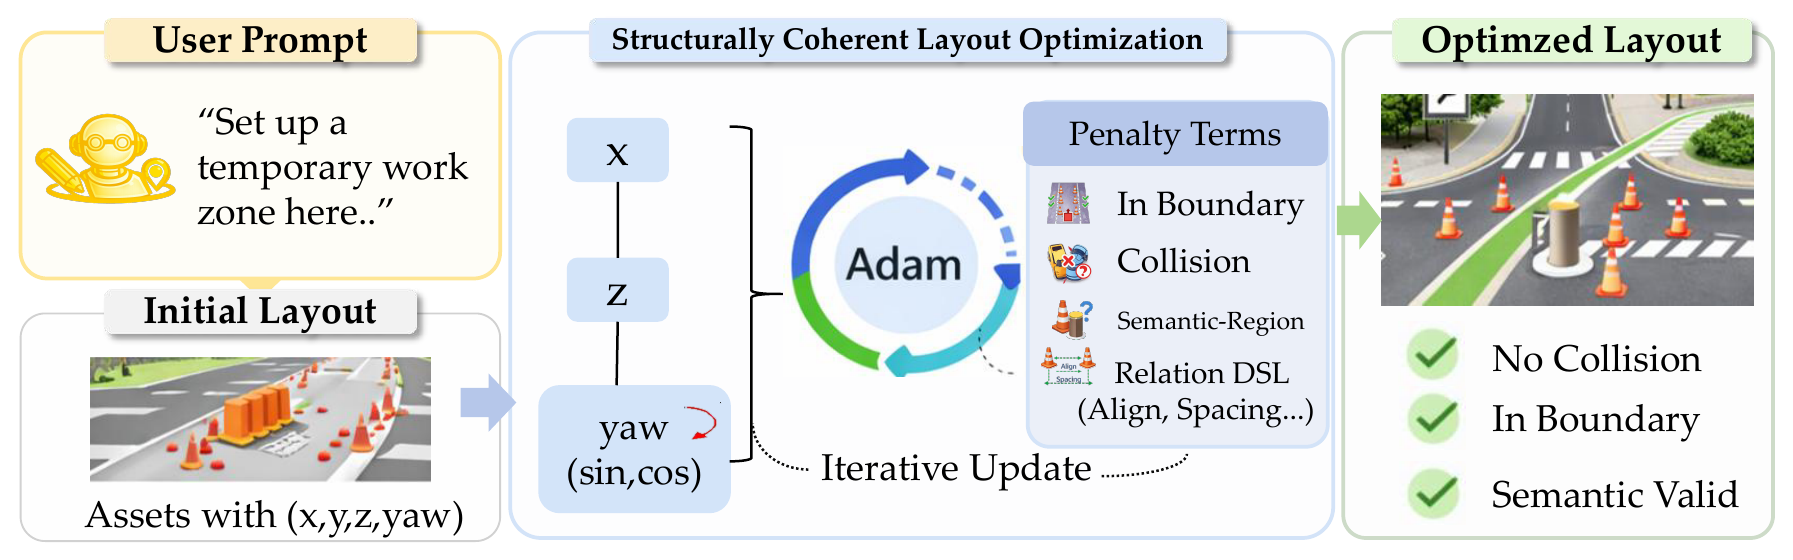
Starting from an initial layout, the module optimizes object positions and orientations under boundary, collision, semantic, and structural constraints to obtain the faithful final layout.
Qualitative, asset, and closed-loop evidence in one compact panel.
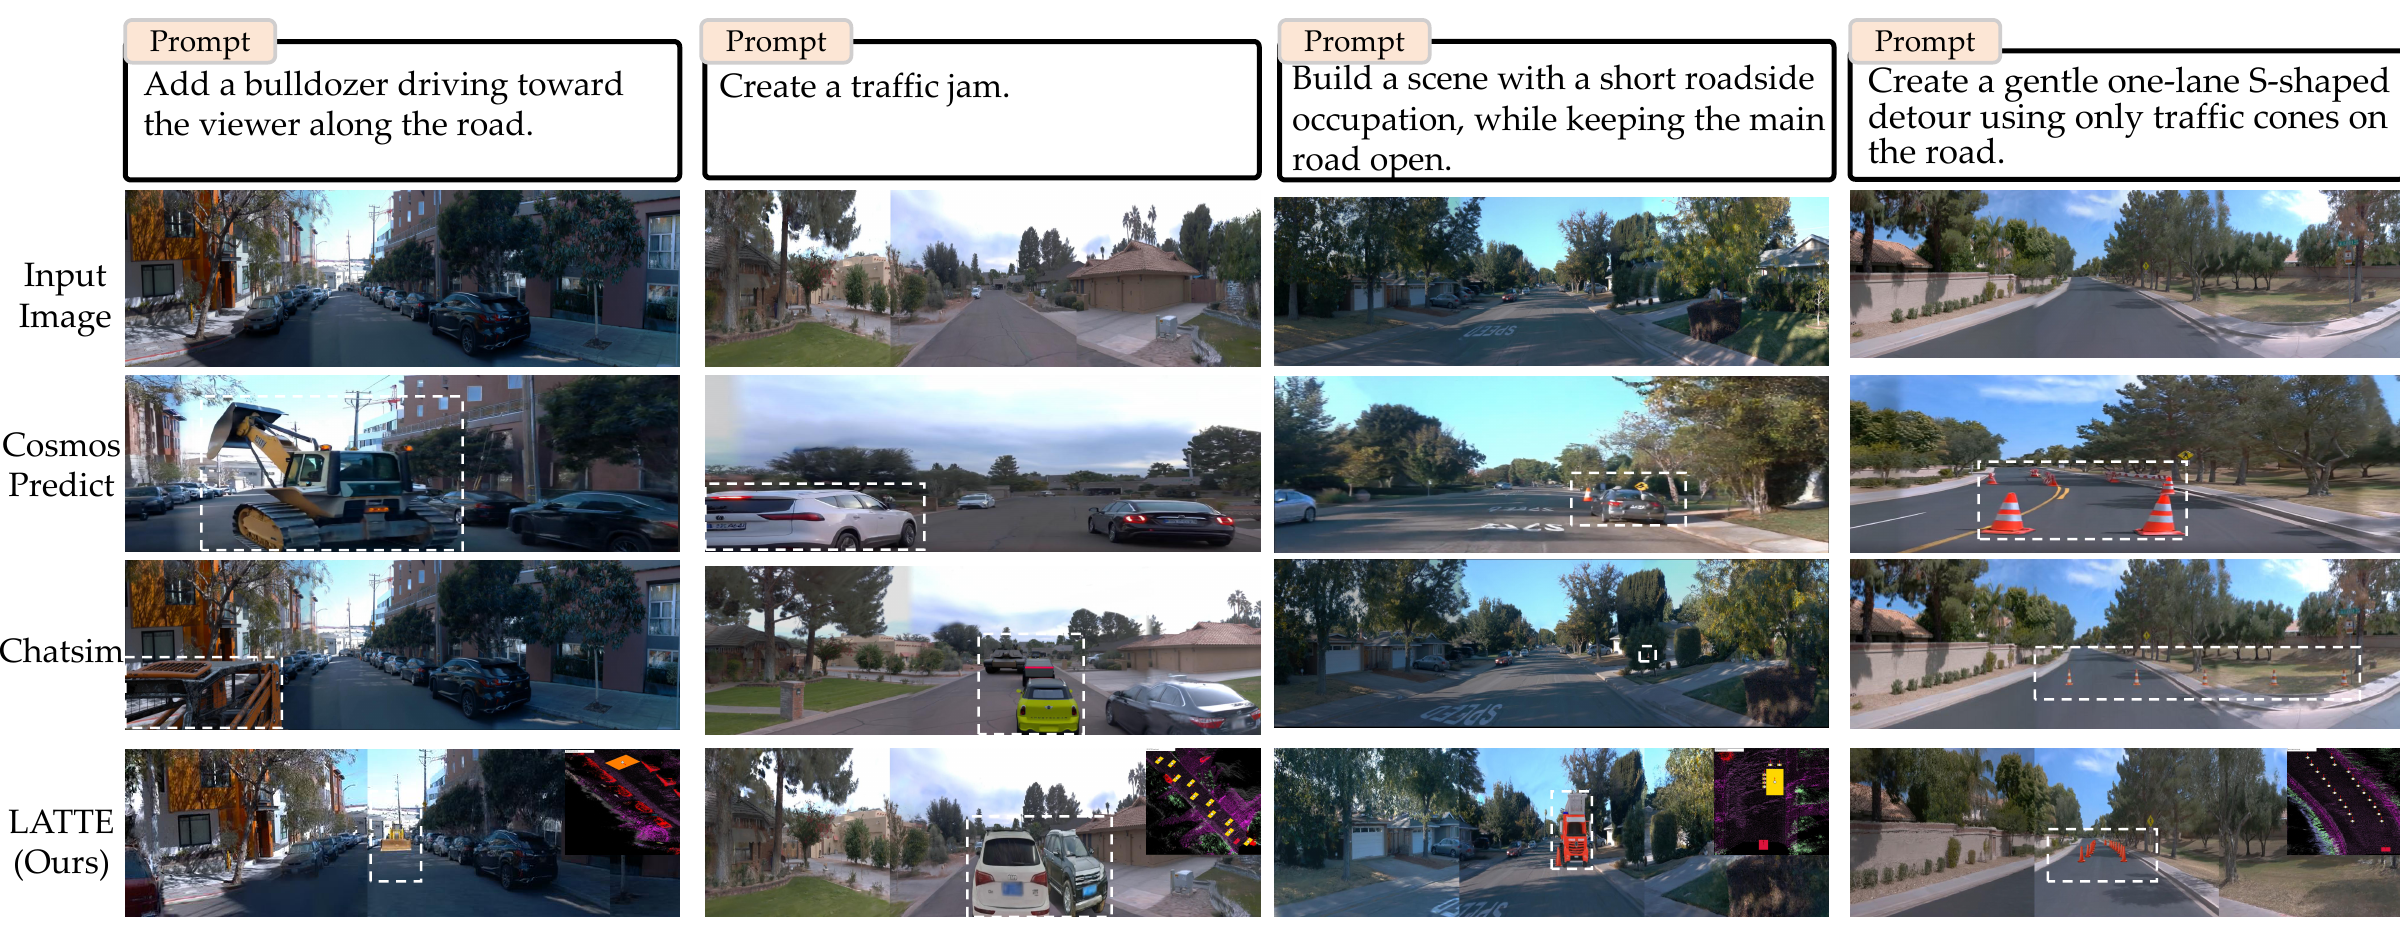
LATTE produces stronger instruction faithfulness and structural organization across open-vocabulary insertion, traffic composition, roadside occupation, and detour construction tasks.
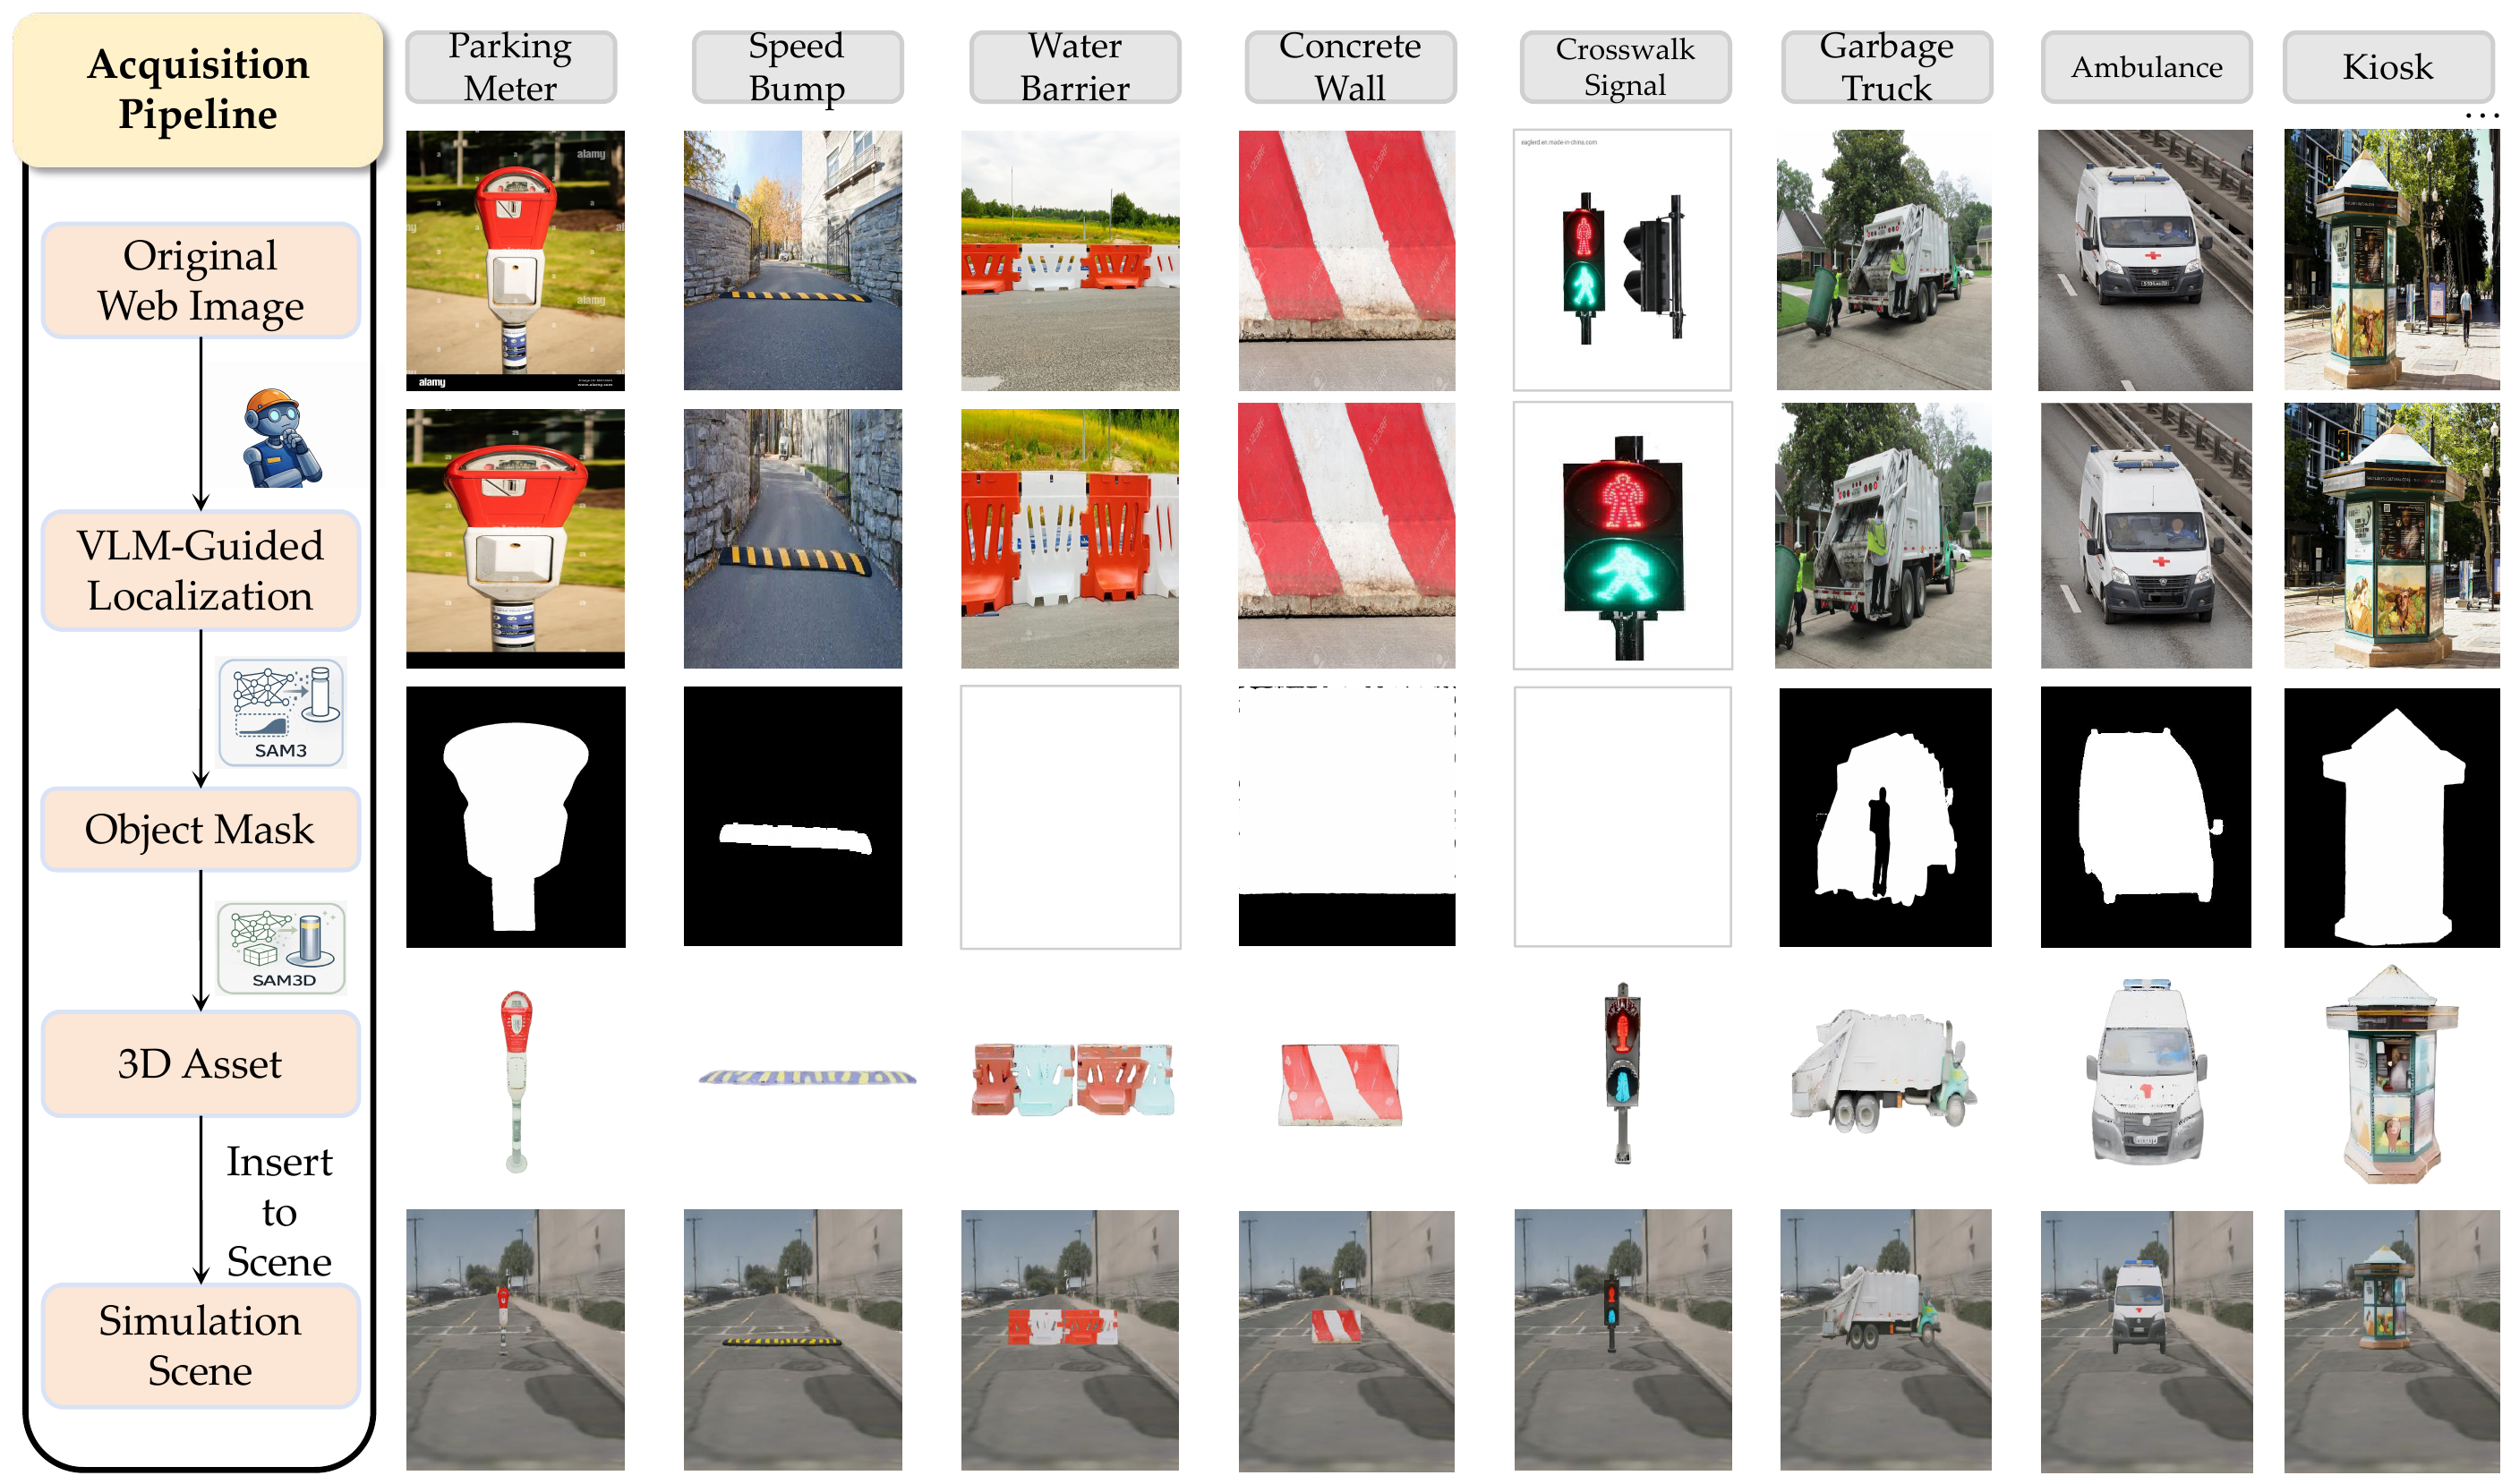
Visualization of the image-grounded asset acquisition pipeline, from web image retrieval and object localization to 3D asset reconstruction and scene insertion.
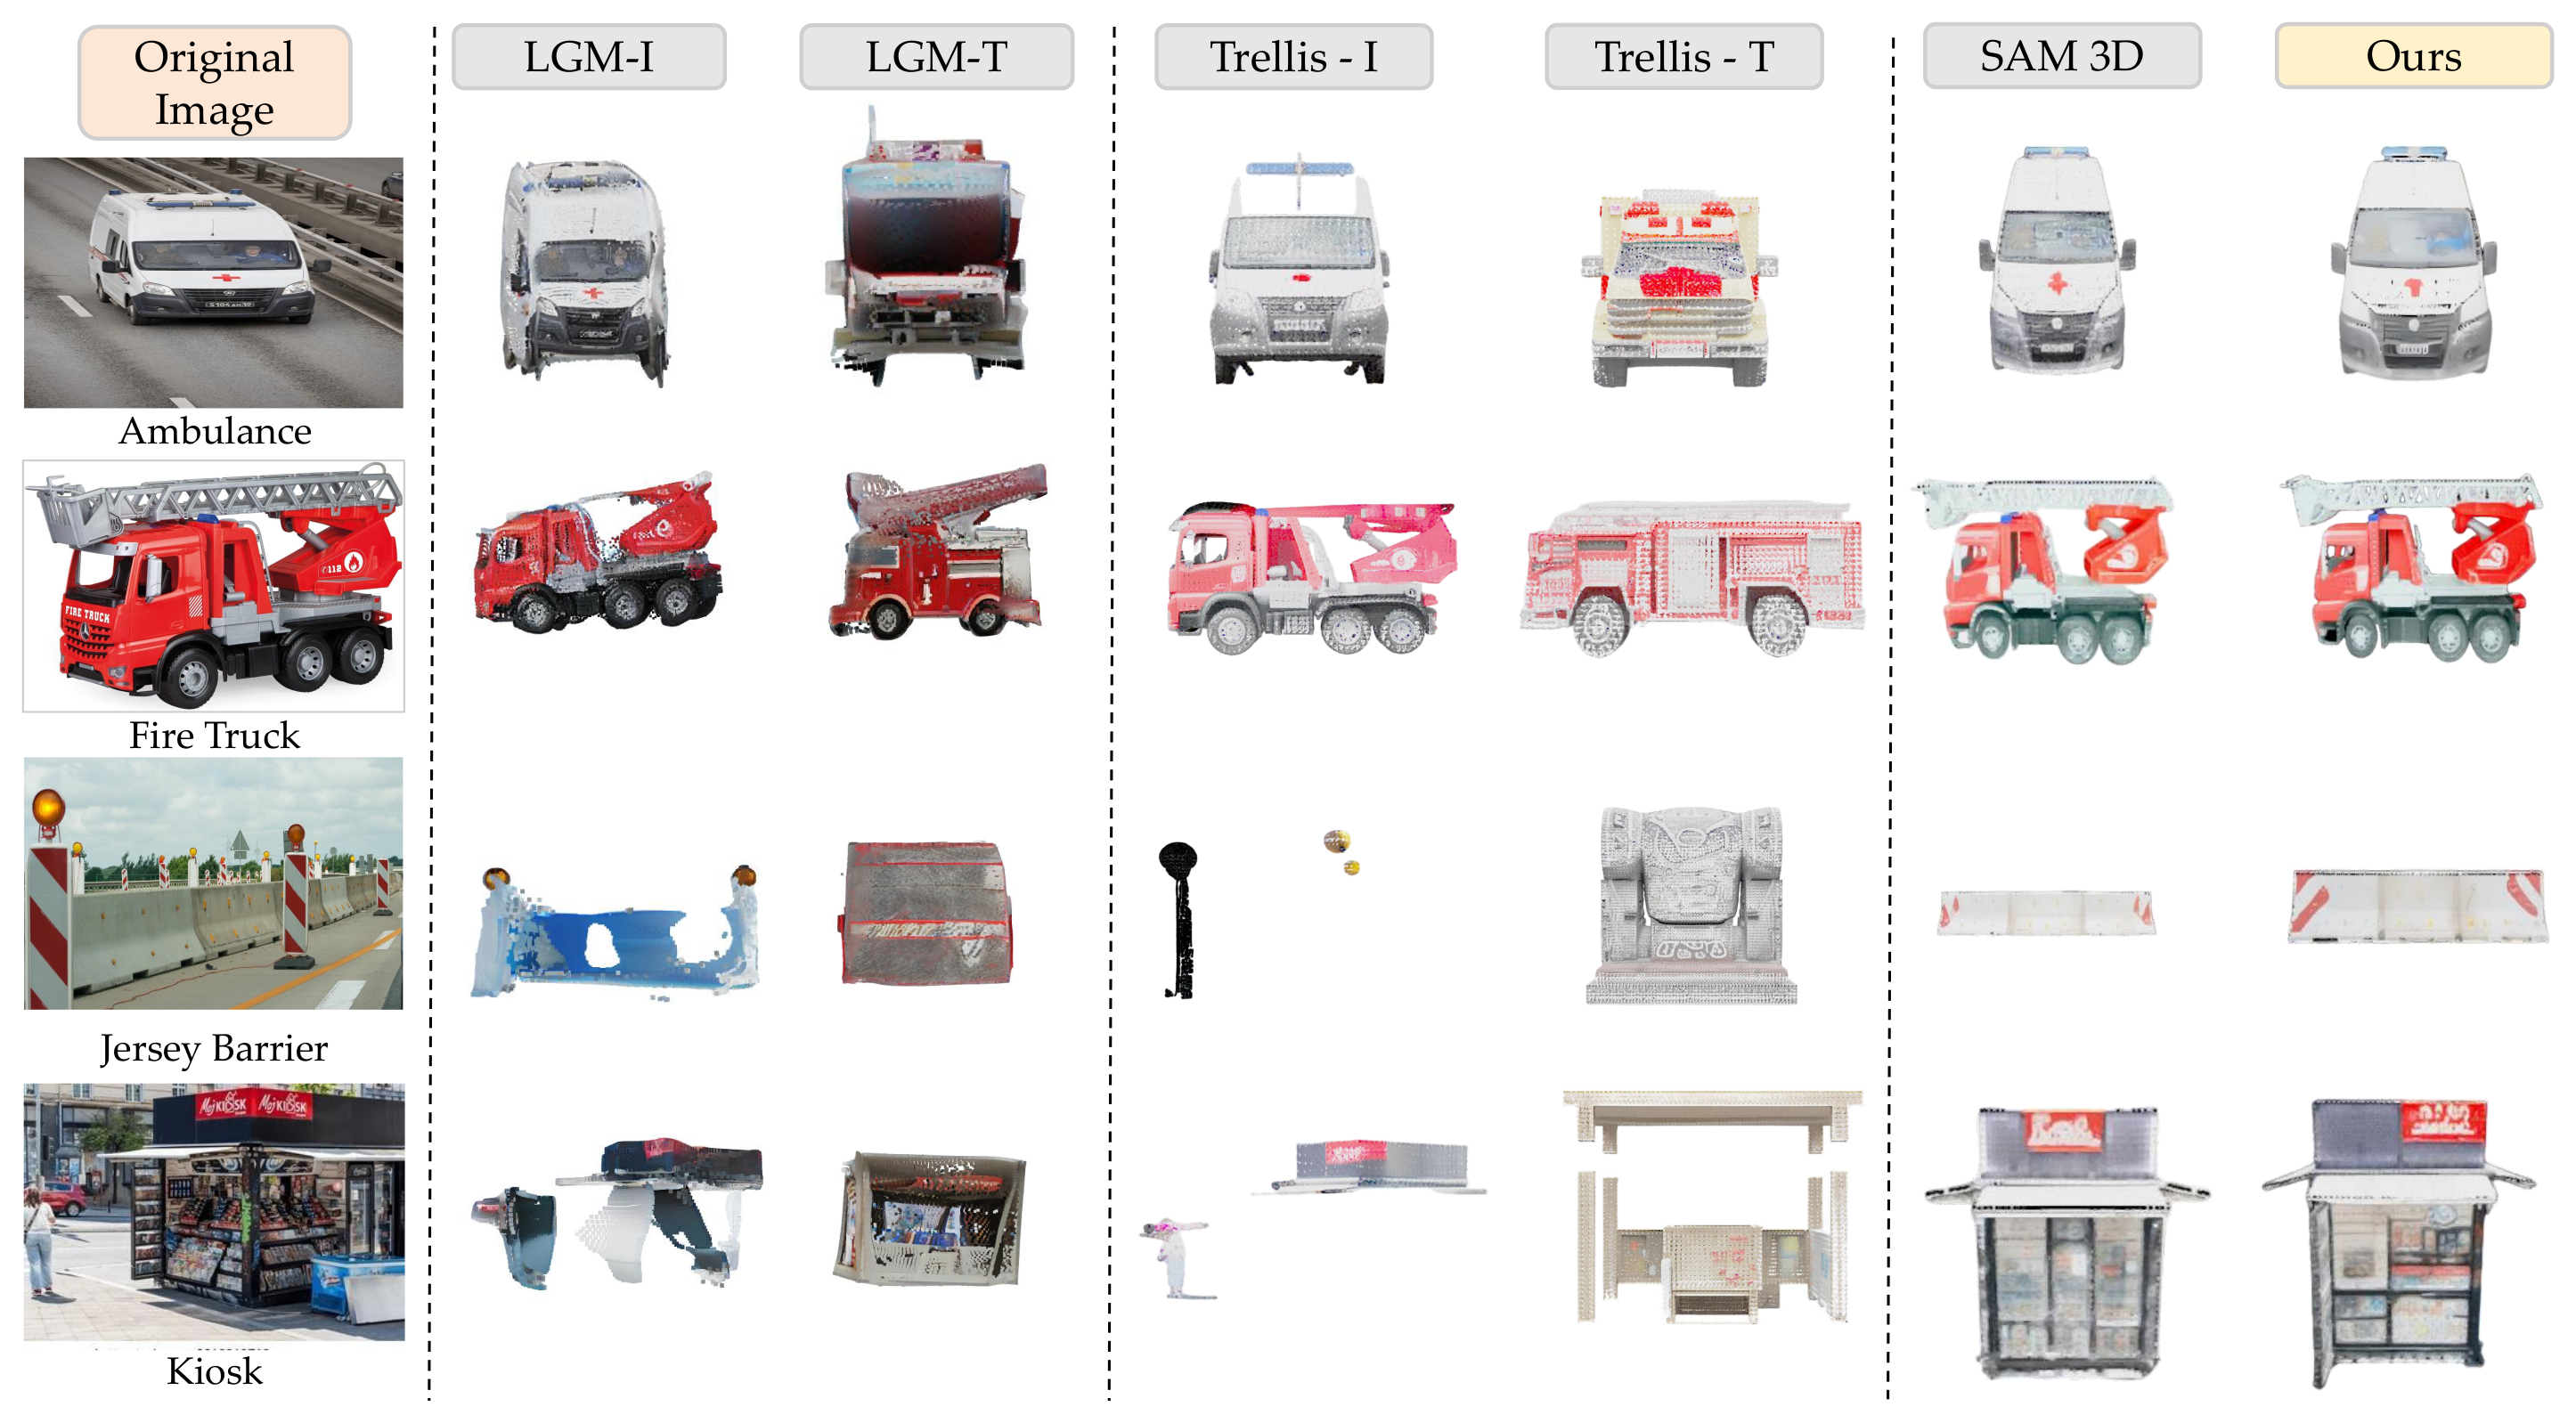
Qualitative comparison of 3D asset construction methods. Our image-grounded pipeline produces more complete and insertion-ready assets.
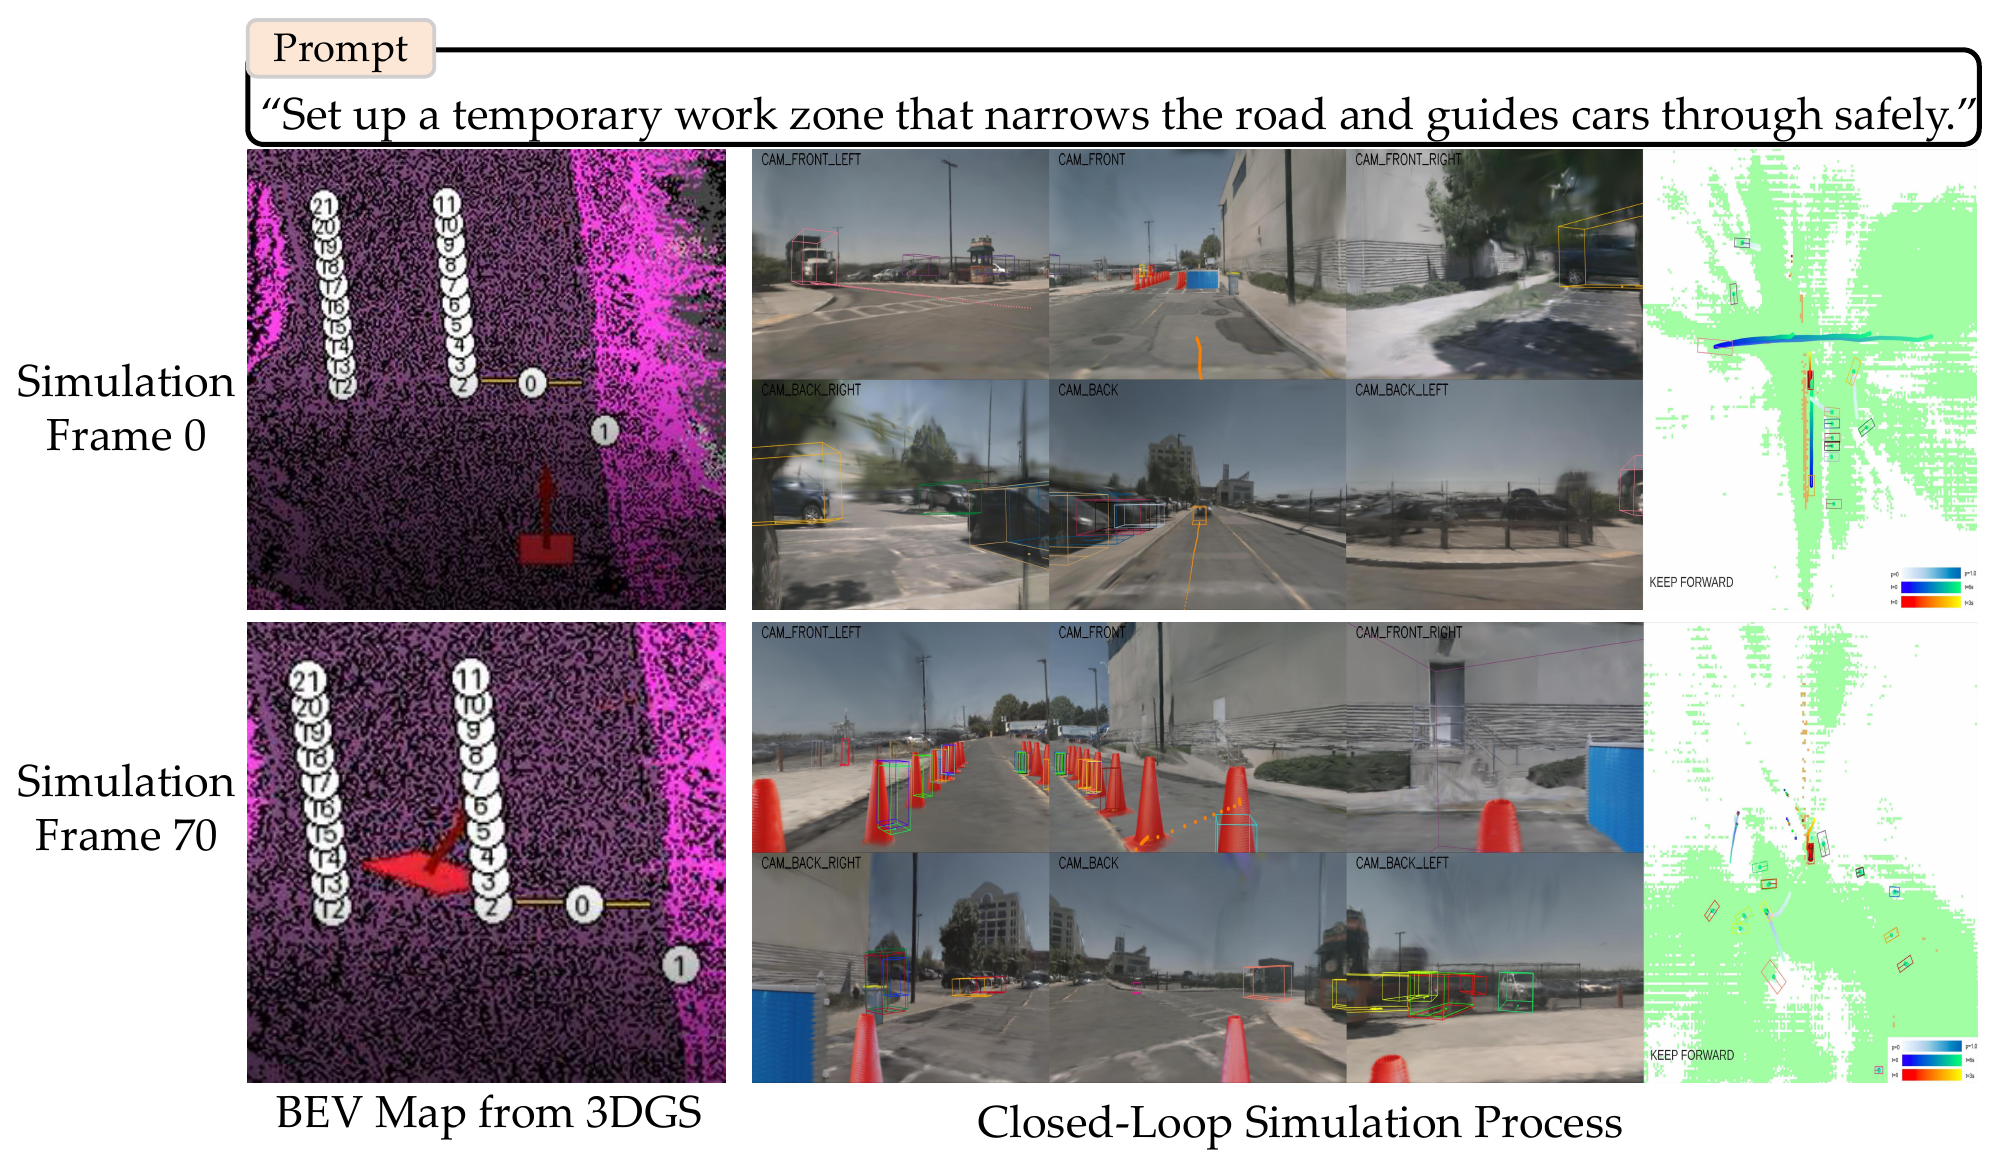
LATTE-edited scenes are evaluated as executable AD test cases rather than only visual edits. The inserted assets and optimized layouts can change trajectories and reduce success- and safety-related metrics under closed-loop rollout.
Paired render and BEV simulation videos for each language-driven edit.
LATTE turns language requests into executable 3D driving-scene edits, while still inheriting open challenges from agent reasoning, open-world asset construction, and scene rendering.
01 Agent reasoning
LATTE is built around a 3D agentic flow: the agent must parse the instruction, understand road topology, reason about object relations, and revise invalid edits. In difficult cases, current VLMs and open-source model APIs still show limited 3D spatial reasoning and driving-scene commonsense, so the editing agent may fail to produce reliable corrections without additional feedback.
Future. A stronger editing agent may require driving-scene edit traces, simulator feedback, and reinforcement learning or task-specific fine-tuning so that correction behavior is learned from executable 3D outcomes rather than only prompted.
02 Asset calibration
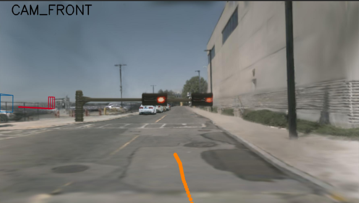
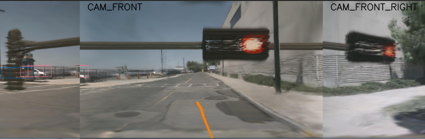
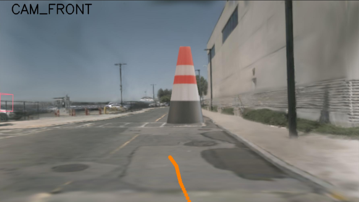
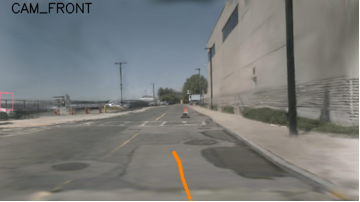
Image-grounded asset construction expands the editable object set, but assets reconstructed from web images are not automatically simulator-ready. Direction, canonical pose, metric scale, and placement-specific calibration still require human verification, especially when the source image gives weak geometric cues.
Future. More automatic pipelines could combine orientation estimation, scale priors, multi-view asset validation, and simulator-in-the-loop calibration to close the gap between single-image reconstruction and directly deployable traffic assets.
Traffic-light insertion
Cone scale calibration
03 Rendering harmonization
LATTE edits a reconstructed 3DGS world and inserts reconstructed 3DGS assets. This preserves an explicit simulation target, but the current prototype does not perform scene-aware harmonization, so inserted objects may look less natural under local lighting, shadow, texture, or boundary conditions.
Future. Multi-view diffusion refinement, illumination-aware 3DGS editing, and rendering-space repair could be added after geometric insertion to improve visual coherence while keeping the scene executable for closed-loop simulation.
@inproceedings{hu2026latte,
  title     = {LATTE: Language-Driven Construction of 3D Driving Scenes for Closed-Loop AD Simulation},
  author    = {Hu, Zaiyi and Wu, Haifeng and Liao, Yiyi and Duan, Lixin and Li, Wen},
  booktitle = {Proceedings of the 34th ACM International Conference on Multimedia},
  year      = {2026}
}